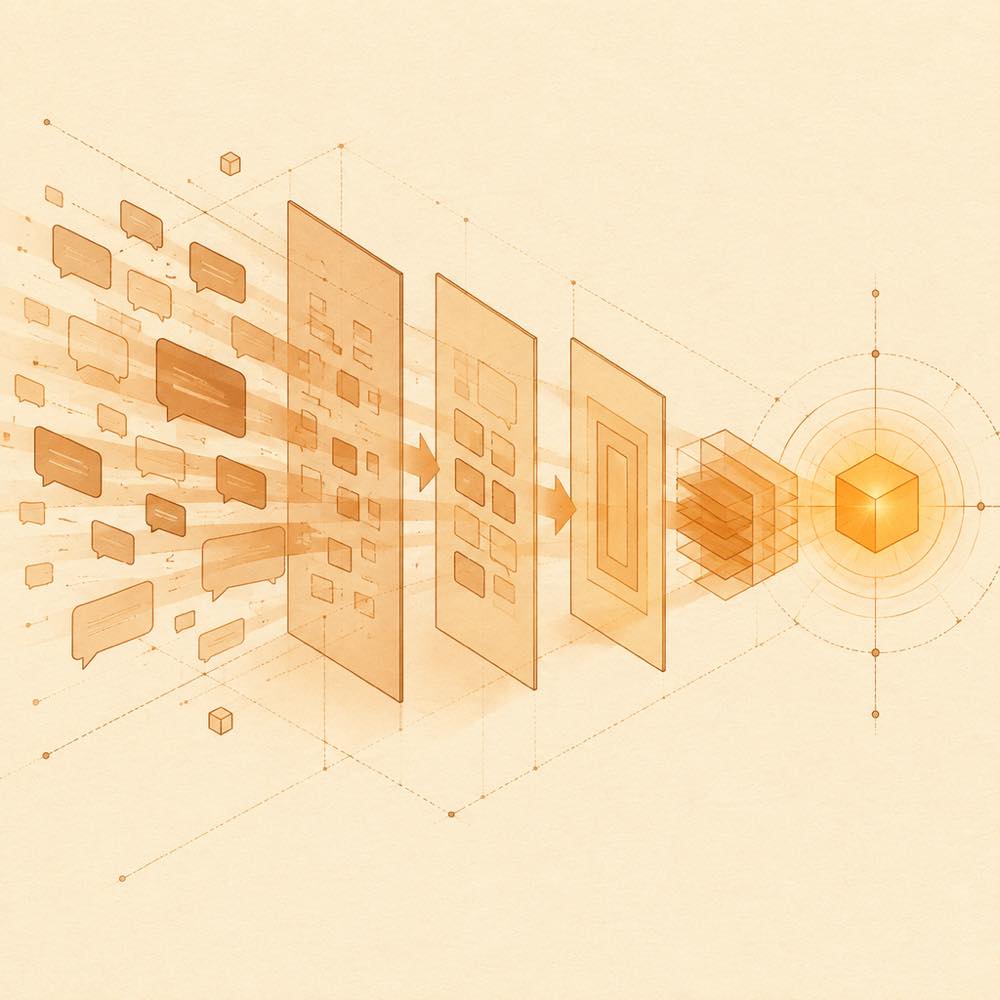
How billion-context works
billion-context sits between an agent and its model API. It rewrites Anthropic and OpenAI streams through acp-kernel, rather than applying a fixed message-count or context-length truncation rule. The model determines when compression should occur and which information should be condensed into summaries. The README describes this as model-driven, incremental, hierarchical compression for long-lived sessions.
The documented purpose is to keep sessions within smaller context windows while reducing repeated input. The project describes 100K as sufficient for its small-window target and reports support for sessions lasting months and reaching billions of tokens. These figures are project claims, not a guarantee for every model or workload.
Commands for billion-context
The README documents two slash commands for checking cache attribution:
They are used when cache health is lower than expected. The README says a healthy session generally has a 95–97% prefix-cache hit rate and that compression itself costs ≤2%; it recommends these commands for investigating attribution.
DeepSeek Harness integration
DeepSeek Harness loads the plugin as a session capability. The provided installation command targets the web profile, but the README excerpt does not document a separate DeepSeek Harness version requirement, configuration key, environment variable, or plugin-specific file path.
Supported stream types and limits
The README explicitly describes rewriting Anthropic and OpenAI streams. It does not establish support for other API protocols, a particular operating system, persistence files, or terminal operations. The catalogue marks a terminal surface, but the supplied documentation does not explain which terminal actions are exposed.
Written from the project's own documentation and kept in sync with it. Where the two disagree, the source is authoritative — read the README on GitHub